Quick Take
- A data clean room lets organizations analyze combined data without seeing each other’s raw records.
- Protections come down to how well the rules are configured.
- Many setups handle structured queries well and struggle with AI training or cross-border data.
- Privacy-enhancing technologies like FHE and federated learning cover what’s beyond that.
A data clean room exists for situations like these: a bank comparing fraud signals with three other banks, a hospital network pooling patient outcomes with two research partners, a government agency cross-referencing records held by a sister department. In every case, the information involved is too sensitive to simply hand over, but too valuable to leave siloed.
This kind of environment lets separate organizations bring their datasets together, run an agreed analysis, and walk away with insights instead of raw records. For teams in government, healthcare, and financial services, that pitch is appealing. But it also raises a fair question: how far does it actually go, and where do its protections end?
This article covers what a DCR is, how it protects privacy, the different types available, and where regulated industries hit the edge of what this approach alone can offer.
What Is a Data Clean Room?
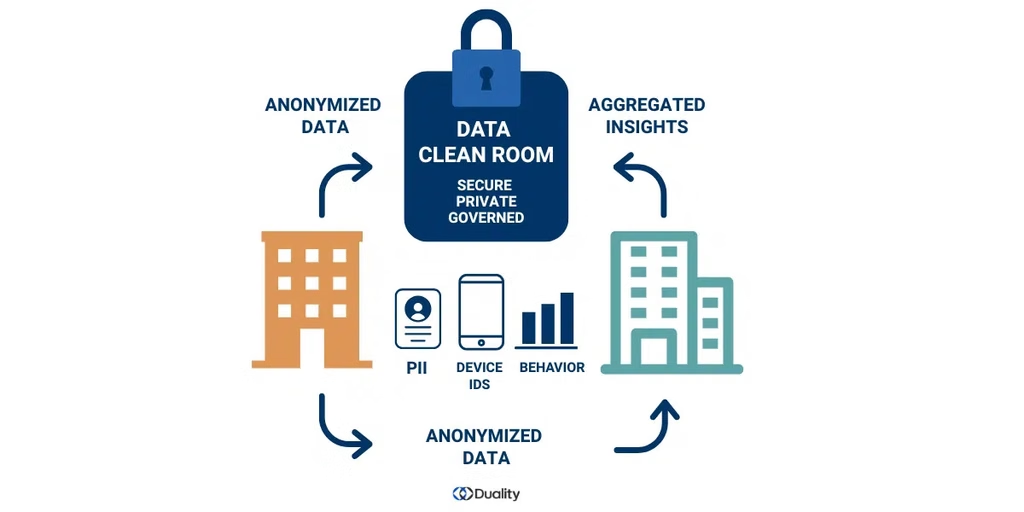
A data clean room (DCR) is a controlled environment where two or more organizations can analyze their combined information without giving each other direct access to the underlying records. Each party contributes to the environment, and a set of rules, called constraints, defines what analysis can run and what results can leave. Nobody sees the other side’s raw records.
The concept started in advertising, where publishers and advertisers needed a way to measure campaign performance without sharing customer identities outright. That use case still exists, but the model has spread well beyond adtech. Retailers use it to work with brand partners, healthcare systems rely on it for research collaboration, and banks use it to compare fraud patterns.
The Federal Trade Commission’s own analysis of the category is a useful reference point here. As the FTC frames it, the constraints are what actually set this kind of environment apart from an ordinary transfer. Get those constraints right, and privacy risk genuinely goes down. Get them wrong, and it becomes a transfer with extra steps.
A national retailer, for example, might want to know if its loyalty members also subscribe to a streaming partner’s premium plan. Inside the shared environment, the retailer learns that a meaningful share of its members do, while the streaming service learns those same members are more likely to buy home entertainment products.
Neither company sees the other’s customer list, and both walk away with aggregated insights they can act on.
Why Data Clean Rooms Have Become Essential for Regulated Industries
Three forces are pushing this model from a nice-to-have into standard infrastructure, and all three land harder on regulated sectors.
Twenty U.S. states have enacted comprehensive consumer privacy laws, each with its own consent rules and compliance requirements. Add GDPR, HIPAA, and sector-specific rules like GLBA for financial services, and organizations handling sensitive information are managing a genuinely fragmented compliance picture.
- Third-party tracking is getting harder to rely on.
Browser-level restrictions and platform policy changes have pushed many industries toward a first party data strategy as the more durable path. A shared, governed environment gives organizations a way to activate that first-party information with partners without exposing it directly.
- Adoption has already gone mainstream.
According to Skai’s 2025 retail media survey, 66% of the organizations surveyed already use data clean rooms in some form. In a typical setup, each party keeps ownership of what it brings, the computation is governed, and only privacy-safe results move between them.
For regulated industries specifically, this answers a question that used to have no good answer: how do you collaborate across organizational lines on information that strict rules govern?
How Data Clean Rooms Protect Privacy
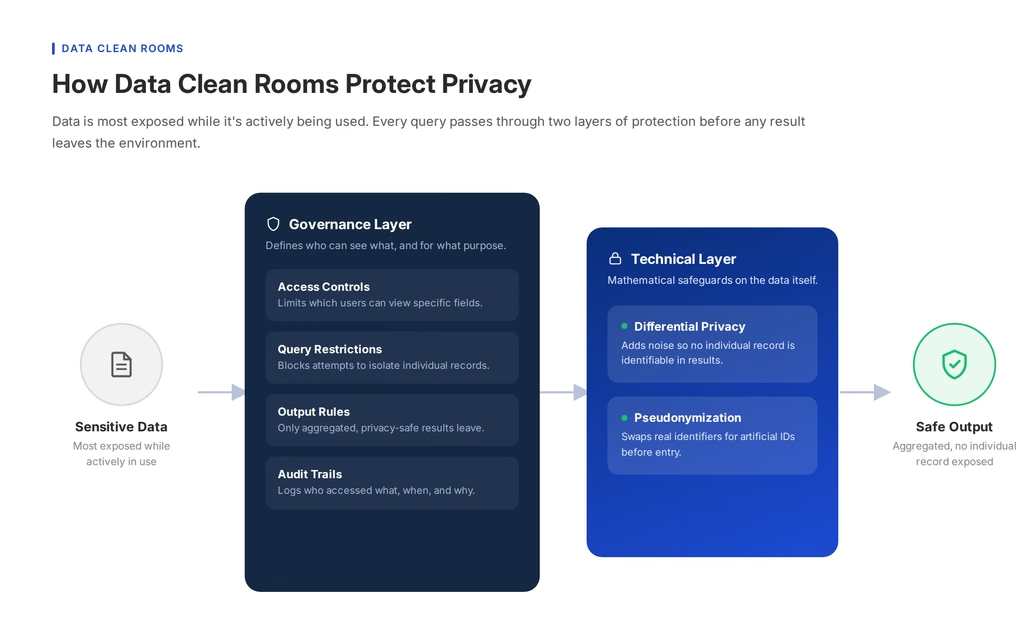
Sensitive information is exposed while it’s actively being used, more so than while it’s sitting in storage or moving between systems. That’s precisely the moment this kind of environment is designed to protect. It does this through a combination of governance rules and technical privacy methods.
Governance and Access Controls
Every deployment runs on a governance layer that defines who can see what, under what conditions, and for what purpose. In practice, this usually includes:
• Access controls that limit which users or roles can view specific fields or datasets.
• Query restrictions that define which types of analysis are permitted and block attempts to isolate individual records.
• Output rules that only allow aggregated, privacy-safe results to leave.
• Audit trails that log who accessed what, when, and why, which matters for compliance reporting as much as security.
These data governance controls are the backbone of the model. Without them, it’s just a shared database with a better name.
Pro tip: Review query logs on a set schedule instead of waiting for an incident to trigger it. Exposure in a clean room often comes from constraints that were fine on day one and never got rechecked as new partners and use cases were added.
Differential Privacy
Differential privacy adds a layer of mathematical noise to query results, making it difficult to identify or infer anything about a specific individual from the aggregate output.
It’s a way of answering a question about a group accurately, while keeping any one person’s record indistinguishable within that group.
Pseudonymization
Pseudonymization replaces direct identifiers, like names or account numbers, with artificial IDs before information enters the environment. Think of it as giving every participant a badge number instead of a name tag: analysts can still track patterns and matches across records using pseudonyms, never real identities.
For a closer look at how this compares with other de-identification methods, see this breakdown of data anonymization techniques.
Together, governance and these technical safeguards are what allow the model to support secure multiparty analytics without either party seeing the other’s underlying records.
Types of Data Clean Rooms
Not every setup works the same way. The right type depends on how much control an organization wants, and how much support it needs running partnerships.
| Type | How it works | Best suited for |
| Walled Garden | Run by a large platform (Google, Amazon, Meta); no cross-platform visibility | Single-platform advertising measurement |
| Self-Service | Organization gets the technology, manages partnerships itself | Teams that want granular control and can absorb the liability |
| Managed Service | Provider manages partnerships on the organization’s behalf | Teams that want less coordination work and less liability |
| Hybrid | Combines the above based on the partnership | Organizations running several types of collaboration at once |
Walled Garden Clean Rooms
Walled gardens are run by large platforms, think Google, Amazon, or Meta, and let advertisers evaluate performance using the platform’s own information. They’re the most widely used type, but they only offer a view inside that one platform.
Self-Service Clean Rooms
A self-service setup gives organizations access to the technology itself, without help managing the partnerships that run inside it. This suits companies that want granular control over their own analysis and have the resources to manage those partnerships and take on the associated liability.
Managed Service Clean Rooms
With a managed service, the provider handles the partnerships on the organization’s behalf. The tradeoff is the opposite of self-service: less liability and coordination work, but typically less access to granular, record-level detail.
Hybrid Models
Many organizations end up combining approaches: a walled garden for platform-specific reporting, a neutral environment for cross-platform work, and a managed or self-service setup for strategic partnerships that need more control. There’s no rule that says an organization has to pick just one model.
Duality’s take: There’s no universal “best” type of clean room. The right choice depends less on the technology itself and more on how much liability your legal and compliance teams are willing to carry for each partnership.
Technologies Commonly Combined With Data Clean Rooms
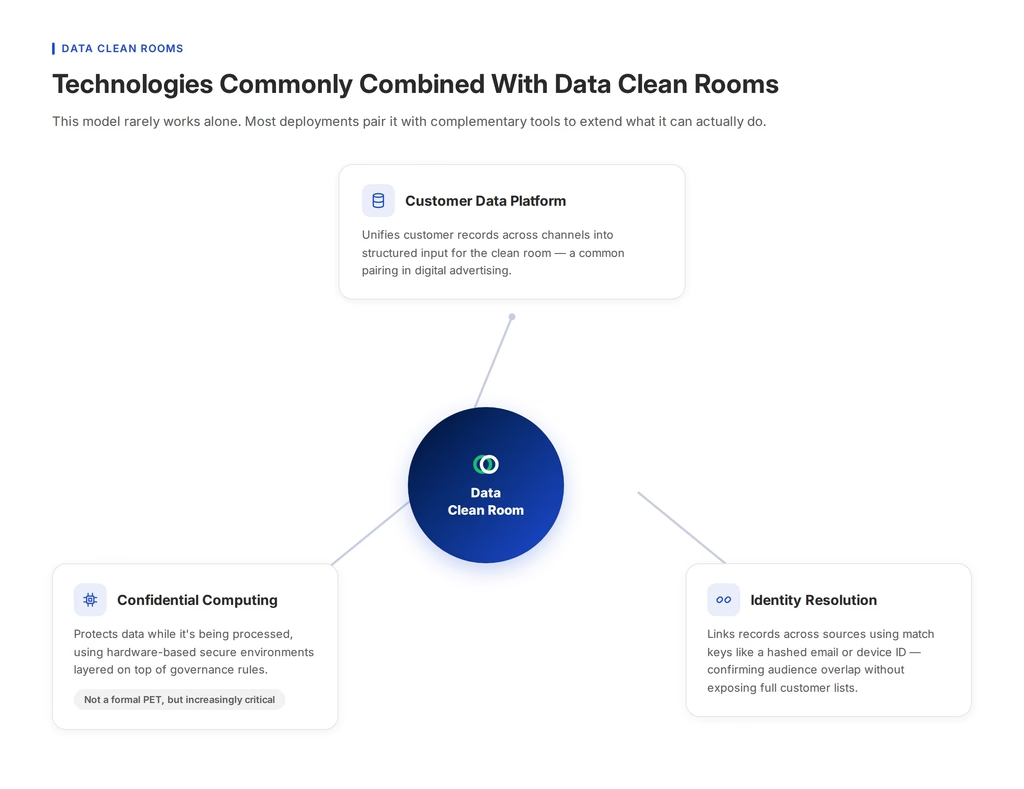
This model rarely works alone. Many deployments pair it with other tools to extend what it can actually do.
Customer Data Platforms
A customer data platform (CDP) unifies a company’s customer records across channels, which makes it easier to feed structured, well-organized input into a shared analysis environment in the first place. It’s a common pairing in digital advertising.
Identity Resolution
Identity resolution links records across sources that refer to the same person, typically using match keys like a hashed email or device ID. Inside a governed environment, this is what allows two parties to confirm an overlap between their audiences without either side seeing the other’s full customer list.
Confidential Computing
Confidential computing protects information while it’s actively being processed, using hardware-based secure environments as a layer on top of governance rules.
Strictly speaking it falls outside the formal definition of a privacy-enhancing technology (PET), yet it’s often viewed as critical when paired with clean rooms and other PETs, adding a technical layer of protection on top of governance controls for workloads that involve highly sensitive material.
Real-World Data Clean Room Applications
Retail and CPG Collaboration
The challenge: A retailer wants to help consumer goods partners measure how digital advertising affects in-store purchases, without handing over raw transaction records.
The approach: A shared, governed environment lets CPG brands match their ad exposure figures against the retailer’s transaction records, producing measurement results without either party seeing the other’s customer-level detail.
Healthcare Research
The challenge: Several healthcare providers want to study a rare disease together, but can’t share patient records across institutions.
The approach: A federated setup allows statistical analysis to run across each institution’s records without patient files ever leaving their source system, supporting research at a scale no single provider could reach alone. Duality’s own work in this space is outlined on its healthcare industry solutions page.
Financial Services Fraud Prevention
The challenge: Banks want to compare fraud patterns to catch bad actors operating across multiple institutions, without exposing customer account information.
The approach: Homomorphic encryption lets a bank check another bank’s records for fraud signals without either side seeing the other’s raw data. This mirrors how Duality supports fraud prevention.
What Data Clean Rooms Cannot Do – and Where They Fall Short
This model is a genuine step forward for privacy safe data collaboration, but it isn’t a guarantee of privacy by default. The FTC’s own review makes this point directly: the protections depend entirely on how well the constraints are designed, implemented, and monitored. A poorly configured setup can expose the same risks as any other transfer, just with a more reassuring name.
A few limits are worth naming clearly:
• Governance has to be actively maintained. Access controls and query restrictions only protect what’s inside if they’re correctly configured and regularly reviewed. A misconfigured environment does not automatically fix itself.
• Outputs can still be reverse-engineered. If results are too granular, or if the same query runs repeatedly against near-identical inputs, it’s possible to infer information about specific individuals even from “aggregated” results.
• Setups are built for structured, tabular records. They’re less suited to unstructured content, real-time processing, or the kind of large-scale AI model training that regulated industries often need.
• Cross-institutional and cross-border collaboration adds friction. Many of these models still expect information to move into a shared environment, which runs into exactly the sovereignty and movement restrictions that government, defense, and financial institutions are trying to avoid in the first place.
• It doesn’t decide what’s compliant. It’s a tool that can support compliance with regulations like GDPR or HIPAA, but the legal and governance work of actually complying with them still falls to the organization.
Worth flagging: If two similar queries return meaningfully different aggregate results on nearly identical inputs, that’s usually a sign the output rules need tightening.
For advertising and retail use cases, these limits rarely matter much. For an intelligence agency comparing records across departments, or a hospital network running cross-border research, they matter a great deal.
What Regulated Industries Use Beyond Data Clean Rooms
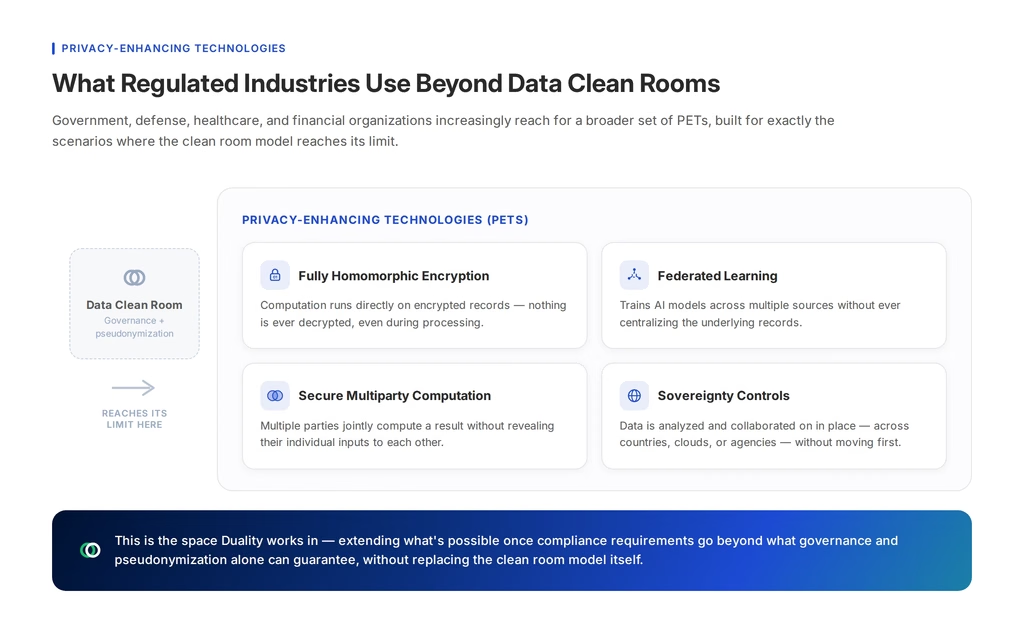
This is where privacy-enhancing technologies (PETs) come in. Government, defense, healthcare, and financial organizations are often turning to a broader set of tools designed for exactly the scenarios where this model reaches its limit.
- Fully homomorphic encryption (FHE) – records stay encrypted throughout the calculation. Only the key holder can decrypt the result, so rules about what results may be shared still apply.
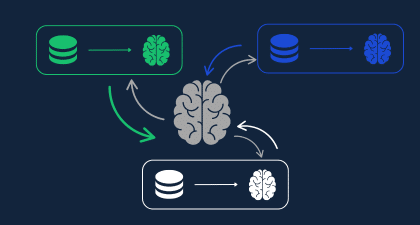
- Federated learning lets organizations train AI models across multiple sources without ever centralizing the underlying records. This addresses one of the clearest gaps in a traditional setup, which was built for queries and joins, and struggles with large-scale model training. Shared model updates can still leak information about the training data, so federated learning is often paired with protections such as differential privacy or encryption.
This is the space Duality works in. These privacy-enhancing technologies extend what’s possible once an organization’s compliance and security requirements go beyond what governance rules and pseudonymization alone can guarantee, without replacing the clean room model itself.
For regulated industries handling classified, protected, or highly sensitive material, that extra layer gives compliance teams more technical evidence to review.
What All of This Means for Your Organization
Data clean rooms solve a real problem: they let organizations collaborate on sensitive information without handing it over outright. For advertising, retail, and many standard partnership use cases, that’s often enough.
For government, healthcare, and financial organizations working with classified, regulated, or highly distributed material, this model is frequently just a starting point. The governance approach that makes it work well for structured queries is the same approach that limits it when the use case involves AI training, cross-border collaboration, or records that legally cannot move at all.
Understanding where that line sits is the first step toward choosing the right combination of tools.
That could mean a clean room on its own, one paired with confidential computing, or a broader set of privacy-enhancing technologies built for the specific compliance and sovereignty requirements your organization has to meet.
For a closer look at where clean rooms hold up well and where they don’t, see Data Clean Rooms: Advantages and Disadvantages.
Duality’s platform brings fully homomorphic encryption, federated learning, and confidential computing together in one place, so organizations don’t have to piece together separate tools to cover what a clean room can’t. That combination gives compliance teams technical evidence to review.